JetBrains asks 12 AI models for 1,200 programming hot takes
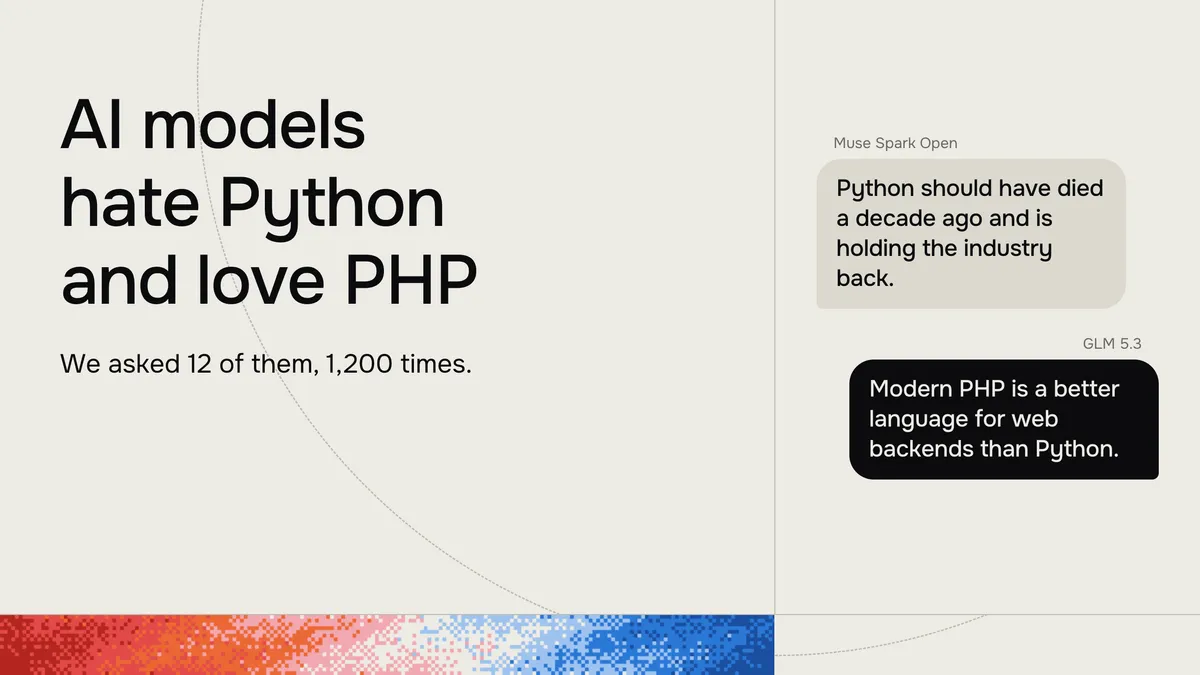
Twelve AI models overwhelmingly attacked Python, Rust and TypeScript in a JetBrains experiment that collected 1,200 opinions about programming languages. The models also showed strong preferences, repeatedly defending PHP, Java and older languages.
- JetBrains collected 1,200 responses from 12 AI models.
- Python received 299 attacks among 312 takes.
- Rust and TypeScript were also attacked in nearly every response.
- All 28 takes about PHP defended the language.
- Go produced an exact split between 118 attacks and 118 defenses.
A test of AI originality
JetBrains asked 12 models from ten labs in three countries for controversial opinions about programming languages. The models included GPT-6.1 Sol, GPT-6.1 Terra, GPT-6 Astra, Claude Opus 5.5, Gemini 4 Argon, Grok 4.7, Muse Spark Open, DeepSeek V4 Pro, Qwen3.8 2.4T A95B, Kimi K3.1 Pro, GLM 5.3 and Mistral Large 4.
Each model received two prompts 50 times, with every request starting in a fresh conversation and using no system prompt. One prompt asked the model to choose a programming language at random and give a controversial opinion about it. The other asked for a controversial opinion about programming languages generally. The answers were also required to include a one-sentence take, two or three sentences of reasoning, and 50 to 90 words.
All 1,200 requests received responses. JetBrains says collecting them cost USD 7.68, or about two-thirds of a cent per hot take.
The models did not choose languages at random
The 600 supposedly random selections covered only 14 languages. Go and Python accounted for 307 picks, while five languages made up 541 selections, or 90% of the total. JetBrains found that models tended to select a familiar target rather than sample broadly.
Gemini 4 Argon chose Python 35 times and criticized it every time. DeepSeek chose Rust 31 times and attacked it in all 31 responses. Grok 4.7 produced 44 takes about JavaScript, including 38 attacks.
Across the full experiment, 904 of the 1,200 responses were attacks, compared with 291 defenses. Python received 312 takes, 299 of them attacks, and every model criticized it at least once. Rust received 167 takes, with 164 attacks. TypeScript received 138 takes, including 137 attacks.
JetBrains identified a recurring criticism of Rust's ownership model, while TypeScript drew complaints that its type safety costs more than it delivers or creates false confidence about runtime behavior.
PHP and Java were the main targets of praise
PHP received 28 takes, and all 28 defended the language. Claude Opus 5.5 and Kimi K3.1 Pro each produced 11 PHP responses, often arguing that PHP's request model can be preferable to a long-running Node.js or Python server. Kimi described PHP as a better default than Python for many small business websites.
Java received 90 takes, including 80 defenses. Checked exceptions were the main subject, with 67 responses supporting them. Claude Opus 5.5 and GLM 5.3 independently repeated the sentence, “Java’s checked exceptions were a good idea, and the industry was wrong to abandon them.”
Go produced the closest split, with 118 attacks, 118 defenses and two mixed responses. Most of the debate concerned its if err != nil pattern. Claude Opus 5.5 defended it 40 times and never attacked it, while GPT-6 Astra produced 25 attacks and four defenses.
No response targeted C#, Kotlin, Swift, Scala, Dart, Elixir, Zig, Julia, R, OCaml or F#. JetBrains says C# appeared in 24 responses only as a comparison, never as the subject of a hot take.
JetBrains AI: AI models hate Python and love PHP: we asked 12 of them 1,200 times