CoreWeave reports first multi-rack NVIDIA Vera Rubin MLPerf results
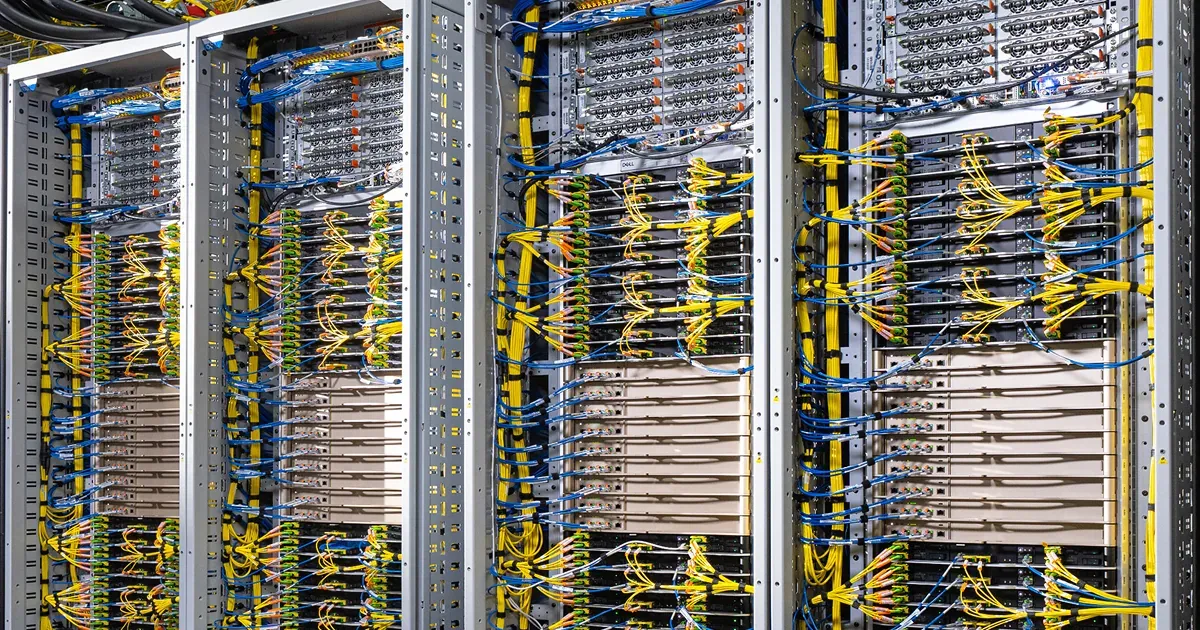
CoreWeave says it is the first cloud provider to deliver multi-rack NVIDIA Vera Rubin results in MLPerf Training v6.1, including a 17.65-minute run for DeepSeek-V3 671B across 256 GPUs. The company also reports the fastest 72-GPU submission in the round for Llama 3.1 8B.
- CoreWeave submitted multi-rack NVIDIA Vera Rubin results in MLPerf Training v6.1.
- DeepSeek-V3 671B reached target quality in 17.65 minutes on 256 Vera Rubin GPUs.
- Llama 3.1 8B took 7.16 minutes on a single 72-GPU Vera Rubin rack.
- Qwen3.5 397B reinforcement learning took 22.78 minutes on 256 GB200 GPUs.
- CoreWeave says its Vera Rubin NVL72 systems are running in production.
Vera Rubin reaches target quality faster
MLPerf Training v6.1 measures how long an AI system takes to train a defined model to a specified quality target. CoreWeave submitted results in the Closed division’s Available category for NVIDIA Vera Rubin NVL72 and NVIDIA GB200 NVL72 systems.
The submissions covered models ranging from 8 billion to 671 billion parameters, with configurations spanning a single 72-GPU rack to 256 GPUs across four racks.
According to CoreWeave, its four-rack NVIDIA Vera Rubin NVL72 system trained DeepSeek-V3 671B, a mixture-of-experts model, to the target quality in 17.65 minutes. Its NVIDIA GB200 NVL72 submission took 48.40 minutes at the same GPU count. CoreWeave calculated that as a 2.7x improvement, while stating that the speedup was derived from published MLCommons results and was not verified by the MLCommons Association.
Fast single-rack result for Llama 3.1 8B
CoreWeave also reported a 7.16-minute time to target quality for Llama 3.1 8B on a single rack of Vera Rubin NVL72. The company described this as the fastest 72-GPU submission in the round, based on its analysis of published MLCommons MLPerf Training v6.1 results.
CoreWeave compared the result with its 13.70-minute GB200 NVL72 submission using the same number of GPUs, calculating a 1.9x improvement. The company said it used NVFP4 GEMMs, FP8 attention and full NVIDIA CUDA graphs on both platforms.
CoreWeave connected its multi-rack systems with a RoCE-based NVIDIA Spectrum-X Ethernet AI fabric, leveraging 102.4 Tb/s Spectrum-6 networking, and NVIDIA ConnectX-9 SuperNICs. It said this infrastructure is intended to reduce communication delays between racks during distributed training.
The wider workload picture
The benchmark submissions also included GPT-OSS 20B reasoning model pretraining and Qwen3.5 397B reinforcement learning on NVIDIA GB200 NVL72. CoreWeave completed the Qwen3.5 workload in 22.78 minutes on 256 GPUs across four racks, using 128 GPUs for training and 128 for generation.
According to CoreWeave, the Qwen3.5 submission is the first large language model post-training benchmark in MLPerf Training. The company said the workload tests coordination between model generation, evaluation and optimization across many GPUs, rather than the workload pattern of conventional pretraining.
CoreWeave said its Vera Rubin NVL72 systems are running in production and that customers can apply the company’s full-stack engineering to multi-rack training workloads. That approach combines compute, networking, orchestration, software and fleet operations, with Mission Control coordinating workload placement and operations across clusters.