Goodfire Finds Small Neuron Communities Behind Model Behaviors
Goodfire Research says small groups of neurons can be necessary and sufficient for specific language-model behaviors, including grammatical agreement, copying and arithmetic. The company’s study presents an unsupervised method for finding these groups without defining their functions in advance.
- Goodfire identified neuron communities that often contain fewer than ten neurons.
- The groups were linked to behaviors including grammatical agreement, copying and arithmetic.
- The method uses attribution, neuron graphs and community detection.
- Tests measured whether communities were necessary and sufficient for predictions.
- The approach was run on Llama-3.1-8B and replicated on Qwen 3.6 35B-A3B.
Small groups can explain model behavior
Neurons are a natural starting point for studying neural networks, but individual neurons can activate in seemingly unrelated contexts. Prompts also activate many neurons at once, making it difficult to separate their contributions.
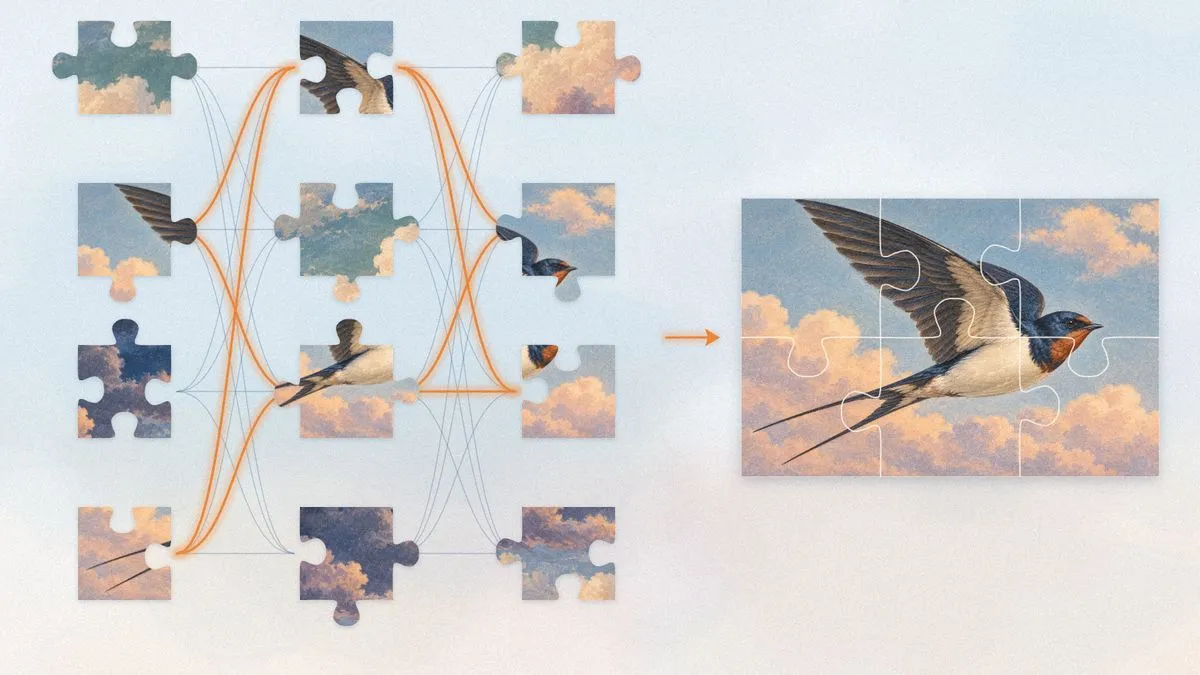
Goodfire’s research examines what it calls neuron communities, small groups that repeatedly work together to implement common model behaviors. According to Goodfire, removing these groups substantially changes a model’s predictions, while retaining them can largely preserve predictions after almost all other MLP neurons in the relevant layers are removed.
Tests on held-out prompts found that these communities are often fewer than ten neurons and can be both necessary and sufficient to explain the contributions of the relevant layers. The study’s examples include grammatical agreement, copying and arithmetic.
An unsupervised method for finding communities
The researchers ran their method on millions of prompts and used gradient-based attribution to estimate which neurons contributed most to each next-token prediction. They then built a graph in which each node represented a neuron, while links represented neurons that repeatedly contributed to the same predictions, adjusted for each neuron’s individual frequency.
Graph community detection was used to identify groups of neurons that repeatedly worked together. The researchers then tested the candidate communities through causal interventions on held-out prompts.
For the necessity test, they removed a community and measured whether the model’s predictions substantially changed. For the sufficiency test, they kept the community while removing the other MLP neurons in the relevant layers, then checked whether the original predictions were largely preserved.
For the reported results, the algorithm was run on Llama-3.1-8B using 10M prompts from FineWeb-Edu, English Wikipedia and FineMath. Goodfire says it later replicated the method on Qwen 3.6 35B-A3B.
A middle layer for interpretability research
Goodfire argues that neuron communities could provide a level of abstraction between individual neurons and higher-order computations. The findings add to evidence that neural networks contain interpretable structure, although that structure may be easier to identify when neurons are studied in recurring groups.
The research also addresses a longstanding challenge from distributed representation, where features can overlap across neurons and give individual neurons multiple roles. Goodfire points to earlier work involving sparse neuron circuits, transcoder features and model sparsification as evidence that some concepts and computations can be captured by surprisingly few neurons.
Because the discovery process is unsupervised, the company says it can be applied at scale without first specifying which behaviors to search for. That could give researchers concrete starting points for investigating neuron functions and testing explanations of how language models produce their outputs. The work does not by itself provide a complete account of neural networks, but it offers a way to move from individual findings toward broader explanations of model computation.
Goodfire Research: Discovering Neuron Communities in Language Models - Goodfire