NVIDIA Puts a Four-Node Supercomputing Lab on Researchers’ Desks
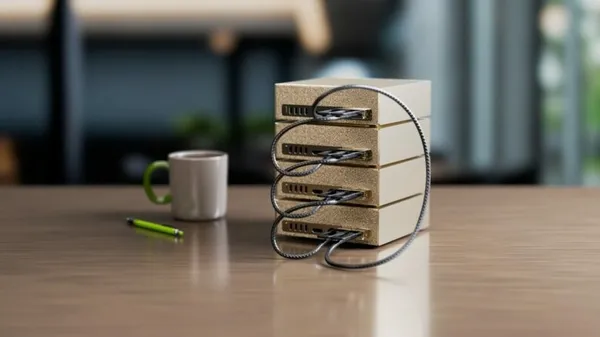
NVIDIA is introducing the DGX Spark HPC Developer Kit, a four-node cluster designed to let researchers, academics and developers run multi-node scientific workloads, AI models and agents at their desks. The company is presenting the kit at SC26, the annual supercomputing conference taking place this week in Chicago.
- The DGX Spark HPC Developer Kit is a four-node cluster.
- Four nodes provide 512GB of combined memory and 20TB of NVMe storage.
- The systems connect directly through NVIDIA ConnectX-7 networking.
- NVIDIA says models with up to 700B parameters can run locally using NVFP4.
- The kit is on display at SC26 and available for sale.
A four-node cluster without a network switch
The kit combines four NVIDIA DGX Spark systems, each connected directly to its two neighbors in a ring through NVIDIA ConnectX-7 networking. According to NVIDIA, users do not need to buy or configure a network switch, and the setup can scale from one system, or node, to four.
At four nodes, the cluster provides 512GB of combined memory and 20TB of NVMe storage. It is built around the GB10 Grace Blackwell Superchip and is intended to give researchers local capacity for distributing models and scientific workloads across multiple systems.
Using NVFP4, NVIDIA says researchers can deploy models with up to 700B parameters locally across the four DGX Spark systems, including DeepSeek V4.1. The company says this can reduce reliance on shared GPU clusters, where researchers may otherwise wait for available computing time.
Tools for scientific computing and AI development
NVIDIA says an installation playbook for the NVIDIA HPC SDK is coming soon. The SDK includes GPU-accelerated C, C++ and Fortran compilers, libraries and message passing interface tools used on NVIDIA-powered supercomputers.
With those tools, teams will be able to build and test scientific applications across four nodes, inspect how computation and data are distributed, and debug communication issues before moving workloads to larger systems. NVIDIA says local development can preserve server capacity for production runs while helping teams keep unpublished results and proprietary datasets on premises.
The company cites demonstrated four-system workloads including LAMMPS with Kokkos for materials simulation and NAMD for molecular dynamics. The broader DGX Spark community has also validated GROMACS for molecular dynamics, OpenFOAM for fluid dynamics, WRF for weather modeling, and NVIDIA NIM microservices including OpenFold3 and Boltz-2 for biomolecular structure prediction.
Examples from quantum research, biology and engineering
NVIDIA describes several research uses for DGX Spark. Kvantify reports using NVIDIA cuQuantum to run tensor-network simulations of quantum-chemistry circuits with up to 70 qubits and 975 gates on a single system. CYRAN AI, an IIT Delhi spin-out, uses DGX Spark and its PixelFlux library to accelerate JPEG 2000 decoding for large satellite images.
OpenFold has used DGX Spark to fine-tune OpenFold3 for protein-ligand structure prediction in drug discovery. At the University of California, Berkeley, the Rubin Lab at IGI is using a DGX Spark and NVIDIA Evo 2 to predict bacterial traits from genome sequences. NVIDIA says results arrived 15x sooner on DGX Spark, without 11-hour cluster queue times.
The Hartwig Group at UC Berkeley is using a DGX Spark for LoRA fine-tuning of the Nemotron 3 Super 120B-A12B model for chemistry machine learning. NVIDIA says the lab fit a 120B-class model on a single device using NVFP4 quantization and ran continuous eight- to 24-hour training fits without multi-day cluster queue times.
Availability and intended impact
The developer kit is on display at SC26 and available for sale. NVIDIA says DGX Spark products and cables can be purchased from top OEM partners and through NVIDIA Marketplace. Listed partners include Acer, ASUS, Dell Technologies, GIGABYTE, H3C, HP, Lenovo, MSI and xFusion.
The forthcoming HPC SDK playbook is intended to give scientists and researchers a local platform for developing multi-node GPU applications, exploring FP32 and mixed-precision algorithms, and running molecular dynamics and materials simulations before scaling to data center systems. The kit therefore targets teams that need a controlled development environment for scientific AI and simulation, rather than replacing larger systems for every workload.