DeepSeek-V4.1-Flash
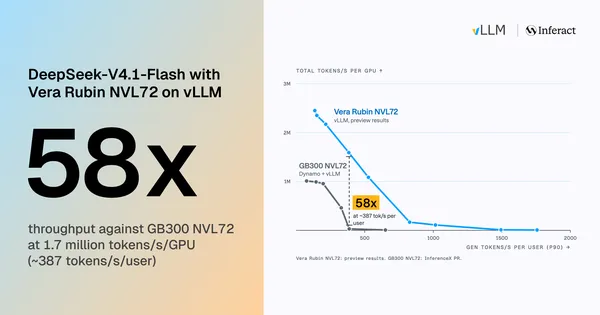
vLLM reports 58x throughput for DeepSeek-V4.1-Flash on Vera Rubin
vLLM says it is serving DeepSeek-V4.1-Flash at 1.7M tokens per second per GPU on an NVIDIA Vera Rubin NVL72 rack, while delivering 387 tokens per second to each user.…
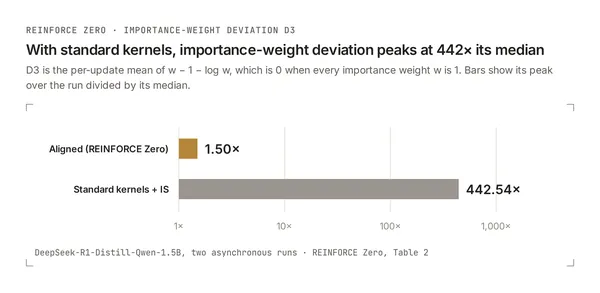
vLLM says aligned kernels make asynchronous RL stable at lag 64
vLLM says aligning the numerical kernels used by rollout and training removes a source of instability in asynchronous reinforcement learning. Its REINFORCE Zero recipe…
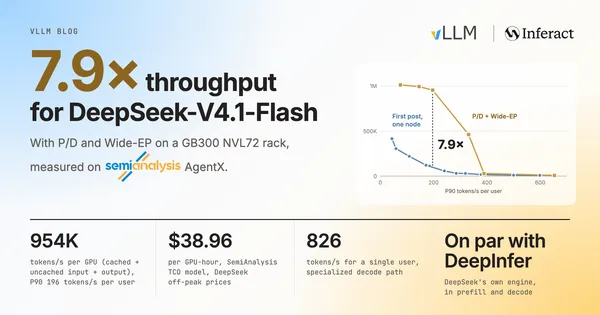
vLLM Hits 954K Tokens/s per GPU on DeepSeek-V4.1-Flash with GB300 NVL72
The vLLM team reports that its engine, running with P/D disaggregation and Wide-EP on one NVIDIA GB300 NVL72 rack, serves DeepSeek-V4.1-Flash at 954K tokens/s per GPU on…
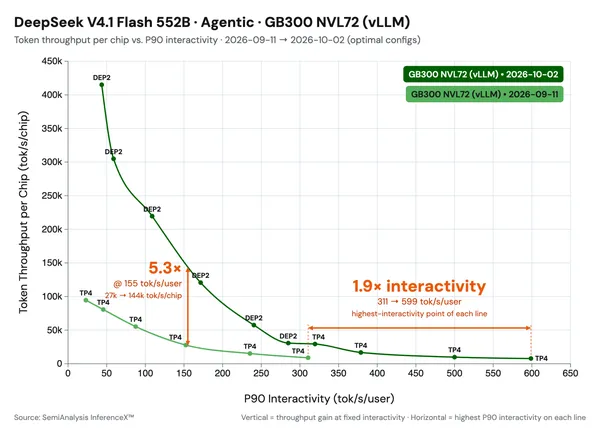
vLLM Gets DeepSeek-V4.1-Flash to 5.3x Throughput in Three Weeks
Inferact and the vLLM community say they have sped up DeepSeek-V4.1-Flash by 1.9x at low concurrency and raised throughput 5.3x under a 150 TPS constraint, within three…