Dynamo
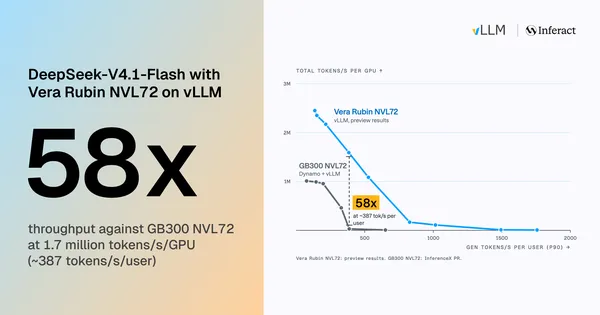
vLLM reports 58x throughput for DeepSeek-V4.1-Flash on Vera Rubin
vLLM says it is serving DeepSeek-V4.1-Flash at 1.7M tokens per second per GPU on an NVIDIA Vera Rubin NVL72 rack, while delivering 387 tokens per second to each user.…
NVIDIA brings Korea’s leading open models to production with Dynamo
NVIDIA is releasing Dynamo-optimized deployment recipes for four of Korea’s leading open models, including models from SK Telecom, LG AI Research, Upstage and Motif…
Hebbia adds memory to Max and conditional logic to Matrix
Hebbia has rolled out memory and version history for its Max assistant, plus new workflow and formatting logic in Matrix. The company's October 2026 update also adds a…
NVIDIA Moves Dynamo Inference Software Into Production for AI Factories
NVIDIA says Dynamo, which it describes as the broadly adopted inference operating system for AI factories, has entered production. The announcement is titled "NVIDIA…