Mooncake
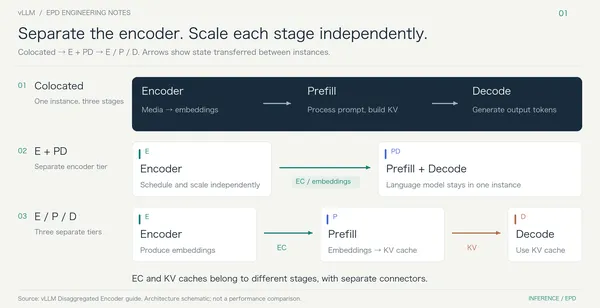
vLLM Expands Encoder Disaggregation for Multimodal AI Serving
vLLM has detailed engineering work that separates multimodal encoding from language-model prefill and decode, allowing operators to scale those stages independently. The…
Furiosa SDK 2026.4 boosts RNGD tokens per watt, adds tiered KV caching
FuriosaAI has released Furiosa SDK 2026.4 for its RNGD accelerator, reporting higher token generation per watt across 18 models compared with SDK 2026.3. According to…
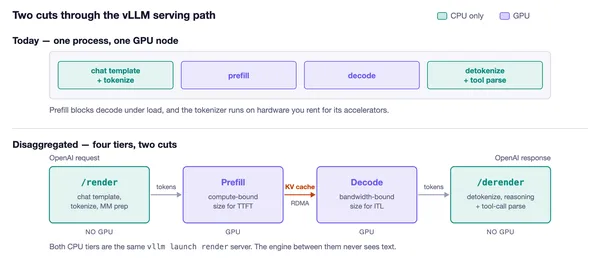
vLLM Guide Shows When Splitting Prefill and Decode Pays Off
The vLLM project has published a practical guide to disaggregated serving, which separates prompt processing, token generation and CPU-side work into different tiers.…