PyTorch
PyTorch 2.15 brings FP8 and much faster MoE decoding to Macs
PyTorch 2.15 adds float8_e4m3fn support on the MPS backend and, according to the Hugging Face PyTorch team, makes mixture-of-experts models decode 5 to 6.5 times faster…
Google and Meta bring TorchTitan to TPUs with PyTorch-native training recipes
Google has released TorchTitan TPU, a fork of Meta's TorchTitan that lets developers train PyTorch models on Google Cloud TPUs with ready-made distributed recipes.…
PyTorch Helion can now tune NVIDIA compiler controls alongside GPU kernel settings
PyTorch's Helion autotuner can now search compiler settings below the kernel level together with its usual kernel configurations. The settings come from NVIDIA's…
TorchNeuron brings native PyTorch support to AWS Trainium chips
PyTorch has introduced TorchNeuron, an open source native backend that lets developers run existing PyTorch code on AWS Trainium by treating the chip as a standard…
Google's LiteRT Tensor API lets developers build on-device models op by op in C++
Google has released the LiteRT Tensor API, a lightweight authoring layer in the LiteRT stack that lets developers build model graphs op by op in C++ and run the same…
TorchNeuron brings native PyTorch support for HF models to AWS Trainium
Hugging Face says its main libraries now run natively on AWS Trainium through TorchNeuron, a new PyTorch backend that exposes Trainium as a standard device. TorchNeuron…
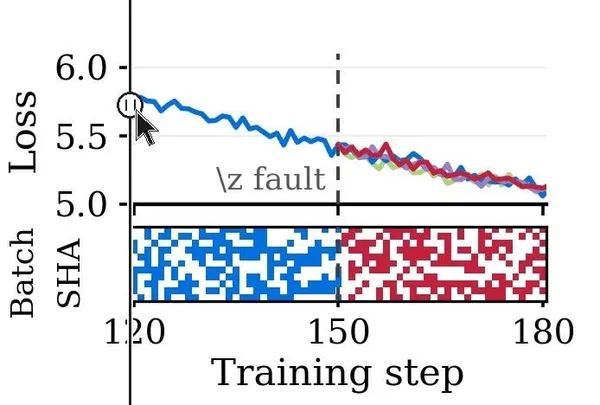
Zephon brings elastically deterministic data loading to PyTorch's TorchTitan
PyTorch has introduced Zephon, a data loader for TorchTitan that produces the same global batches no matter how many GPUs a job runs on, while tokenizing, packing…
ExecuTorch Adds Cortex-M Backend to Run PyTorch Models on Microcontrollers
PyTorch has added a Cortex-M backend to ExecuTorch, allowing PyTorch models to run directly on Arm Cortex-M CPUs with CMSIS-NN acceleration. According to the PyTorch…
IBM's Spyre Accelerator Moves to PyTorch Inductor With a Compiler 7x Smaller
The PyTorch-based software stack for IBM's Spyre accelerator has moved its torch.compile backend from sendnn, a compilation stack built from scratch, to…
NVIDIA Dynamo adds session IDs so inference servers can follow AI agents
NVIDIA Dynamo now ties an agent's many model calls together with a single session-level identifier, so the inference server can treat them as one program rather than…
IBM's Spyre AI Accelerator Becomes a Native PyTorch Device via torch-spyre
IBM's torch-spyre team has detailed how Spyre, its dataflow AI accelerator, works as a native PyTorch device. According to the PyTorch blog post, the integration…
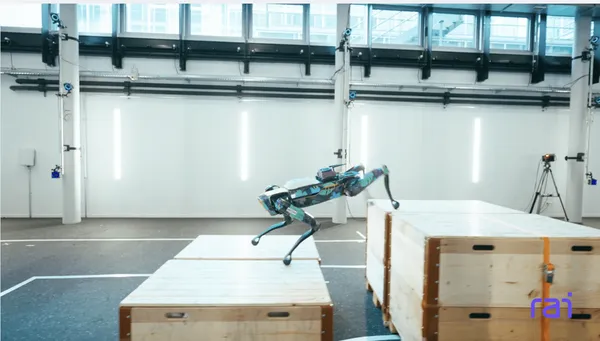
RAI Institute Releases Exploy to Ease Robot Policy Deployment
The RAI Institute has introduced Exploy, an open-source library that exports a reinforcement learning policy together with its full environment logic as one…
For developersPyTorch's FBTriton Kernels for Table Batched Embeddings Beat Legacy CUDA
PyTorch has published a technical walkthrough of FBTriton, a Triton-based implementation of the Table Batched Embedding (TBE) forward and backward kernels used in…
For developersPyTorch Consolidates Media Processing Around TorchCodec, TorchVision and TorchAudio
PyTorch has consolidated its media stack so that TorchCodec handles all decoding and encoding of images, video and audio, while TorchVision and TorchAudio concentrate on…
Chips and infrastructurePyTorch Accelerator Group Reports H1 2026 Progress on Testing and CI
PyTorch's Accelerator Integration Working Group has published a report on its first-half 2026 work, centered on a new Cross-Repository CI Relay (CRCR) and a large…
For developersHelion Brings Autotuned GEMM Kernels to vLLM, Beating CUTLASS and DeepGEMM on Hopper
The PyTorch team has integrated Helion, its Python-based kernel DSL, into vLLM's linear backend. According to the team, on NVIDIA Hopper GPUs it outperforms the vLLM…
For developersPyTorch Launches Certification Pathway Bundling Courses and PTCA Exam
PyTorch has introduced a PyTorch Certified Associate (PTCA) Certification Pathway, which packages four self-paced learning modules and the PTCA exam into a single…
ResearchMeta's TLX Jagged Flash Attention Beats FA4 on Blackwell With 3x Less Code
Meta's team has built a Jagged Flash Attention (JFA) kernel for NVIDIA Blackwell B200 using TLX (Triton Low-level Extensions). According to the PyTorch blog post, it…
Modal Clusters reach general availability with one-line multi-node GPU access
Modal has made Modal Clusters generally available, letting developers run multi-node GPU workloads through a single decorator, @modal.clustered. According to the…
NVIDIA Dynamo-Triton Gets End-to-End HSTU Generative Recommender Workflow
NVIDIA Dynamo-Triton, formerly Triton Inference Server, now supports an end-to-end inference workflow for Hierarchical Sequential Transduction Unit (HSTU) generative…