vLLM
PyTorch Helion Adds Compile-Time Heuristics to Cut Autotuning Delays
PyTorch’s Helion now uses compile-time heuristics to select kernel settings without running slow autotuning searches. The system analyzes a kernel’s intermediate…
PyTorch team integrates SGLang with IBM Spyre in less than a week
A two-person team integrated SGLang with IBM Spyre in less than a week, using AI coding agents to build an open source plugin of roughly 1,500 lines. PyTorch says SGLang…
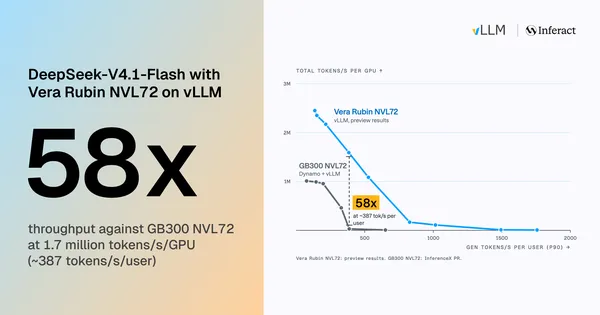
vLLM reports 58x throughput for DeepSeek-V4.1-Flash on Vera Rubin
vLLM says it is serving DeepSeek-V4.1-Flash at 1.7M tokens per second per GPU on an NVIDIA Vera Rubin NVL72 rack, while delivering 387 tokens per second to each user.…
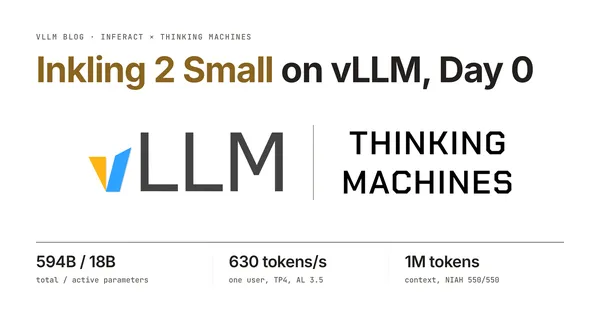
vLLM Adds Day-One Support for Thinking Machines’ Inkling 2 Small
vLLM has added day-zero support for Thinking Machines’ Inkling 2 Small, a multimodal mixture-of-experts model that accepts text and images and produces text. The…
vLLM brings MiniMax H3-Image to Vera Rubin for subsecond 4K generation
vLLM says its implementation of MiniMax H3-Image reaches a median response time of 0.87 seconds for native 4096×4096 image generation on four NVIDIA Vera Rubin GPUs. A…
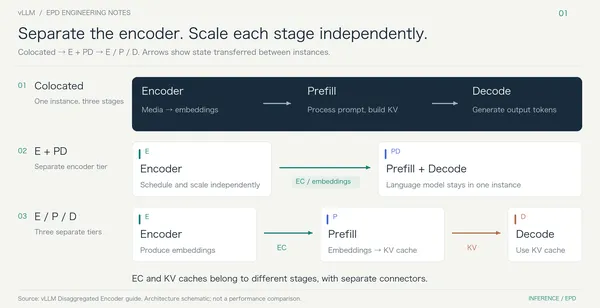
vLLM Expands Encoder Disaggregation for Multimodal AI Serving
vLLM has detailed engineering work that separates multimodal encoding from language-model prefill and decode, allowing operators to scale those stages independently. The…
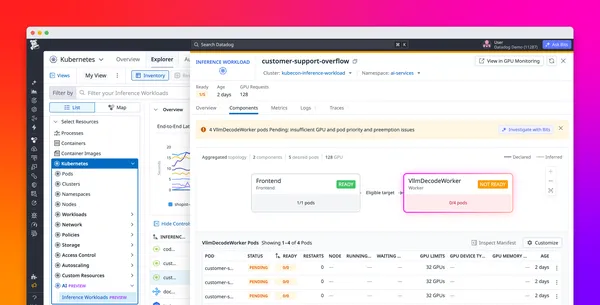
Datadog adds Kubernetes inference workload monitoring in Preview
Datadog has introduced its Kubernetes inference workload feature in Preview, giving engineers a consolidated view of model configuration, serving components, pod state…
vLLM adopts LibTorch Stable ABI to ease PyTorch upgrades
vLLM has migrated its CUDA build to PyTorch’s LibTorch Stable ABI, allowing its v0.33.0 LibTorch ABI Stable CUDA wheels to work across compatible PyTorch releases…
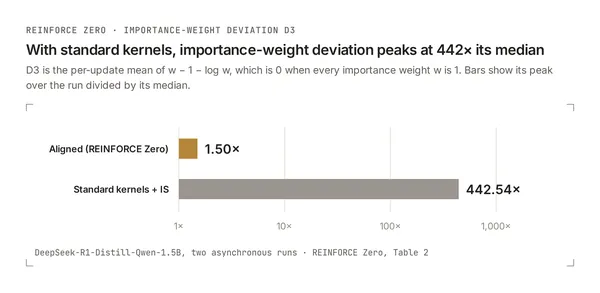
vLLM says aligned kernels make asynchronous RL stable at lag 64
vLLM says aligning the numerical kernels used by rollout and training removes a source of instability in asynchronous reinforcement learning. Its REINFORCE Zero recipe…
Kinference: Buoyant Releases Open Source Inference Control Plane for vLLM
Buoyant has released Kinference, an open source control plane for building inference platforms on vLLM and Kubernetes. According to the company, its KV-cache-aware load…
vLLM Adds Day-0 Support for Moonshot AI’s Kimi K3.1 Pro
vLLM has added day-0 support for Moonshot AI’s Kimi K3.1 Pro, an open-weight multimodal mixture-of-experts model with 2.8T parameters and a 1M-token context. The serving…
Patronus AI Details In-House Post-Training Stack and First Results on Qwen3.8-27B
Patronus AI has published a writeup of the post-training stack it built in-house, along with first results from training the open-weight model Qwen3.8-27B. According to…
vLLM adds day-0 support for Mistral Large 4, a 1-trillion-parameter MoE model
The vLLM inference project now supports Mistral Large 4 from day 0. According to vLLM, the model is Mistral's new frontier mixture-of-experts, natively multimodal model…
Baseten Serves Qwen3-ASR 7x Faster for Batch Transcription
Baseten says its optimized serving stack for Qwen3-ASR 1.7B transcribes 7x more audio per second than out-of-the-box vLLM at high concurrency on a single RTX PRO 6000.…
Cline hits 11,840 tokens per second on one GPU with Nemotron 3.5 Super VL
Cline says it reached 11,840 aggregate output tokens per second on a single GB300 running NVIDIA's Nemotron 3.5 Super VL with 256 concurrent requests. The team published…
vLLM Adds Day-0 Support for MiniMax-M3.1-Flash on NVIDIA and AMD GPUs
The vLLM project says it supports MiniMax-M3.1-Flash from day 0 on NVIDIA Blackwell and Rubin GPUs and on AMD MI350-series GPUs. According to vLLM, the model is built…
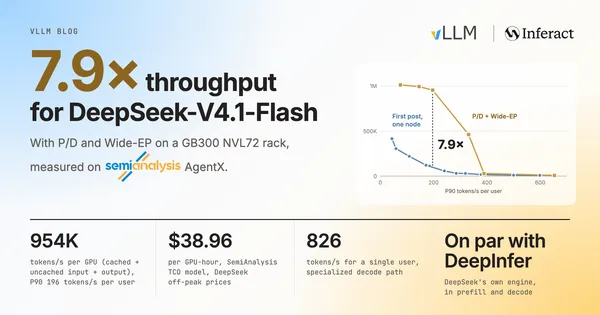
vLLM Hits 954K Tokens/s per GPU on DeepSeek-V4.1-Flash with GB300 NVL72
The vLLM team reports that its engine, running with P/D disaggregation and Wide-EP on one NVIDIA GB300 NVL72 rack, serves DeepSeek-V4.1-Flash at 954K tokens/s per GPU on…
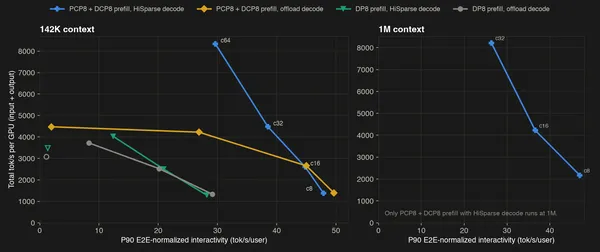
vLLM pairs PCP and DCP to serve 1M-token GLM-5.3 contexts on 16 H200s
The vLLM team says a combination of Prefill Context Parallelism (PCP), Decode Context Parallelism (DCP) and Hybrid HiSparse lets GLM-5.3 serve 1M-token contexts on 16…
PyTorch Foundation names 24 ambassadors for 2026 across five regions
The PyTorch Foundation has named its 2026 Ambassador Program cohort: 24 community leaders across five program regions. According to the Foundation, they will run…
CoreWeave adds official SkyPilot support for multi-cloud AI workloads
CoreWeave has added official support for SkyPilot, an open-source orchestration framework, so teams can run AI training, development and serving workloads on CoreWeave…
Vultr joins Agentic AI Foundation as Gold member to push open agent stacks
Cloud infrastructure provider Vultr has joined the Agentic AI Foundation (AAIF) as a Gold member. The company says it will support the foundation's work on open…
Safety and ethicsIBM Research touts runtime monitoring plugin amid inference push
IBM Research has published a blog post titled "A new plugin can enable fast runtime monitoring and control". The text available for this report contains only the…
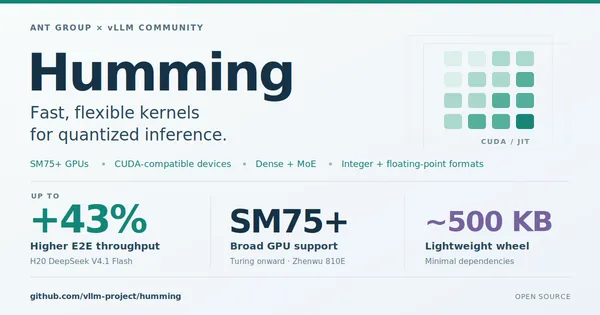
Ant Group and vLLM open-source Humming, a kernel library for quantized inference
Ant Group and the vLLM community are open-sourcing Humming, a general-purpose, high-performance kernel library for quantized inference. According to the project, it…
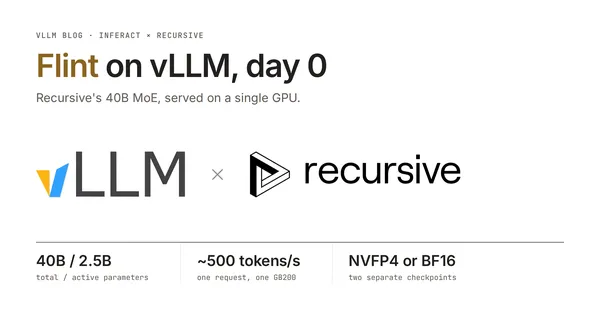
vLLM adds day-0 support for Recursive's Flint, hitting about 485 tokens/s on one GB200
The vLLM inference engine now supports Recursive's Flint from day 0, with both the NVFP4 and BF16 checkpoints running on a single GPU. According to the vLLM team, a…