Z.ai
SambaNova brings Z.ai’s GLM-5.3 to SambaCloud at over 200 tokens/s
SambaNova says Z.ai’s GLM-5.3 is now available on SambaCloud at over 200 tokens per second, giving developers access to an open-weight model designed for long-horizon…
Vercel adds GLM 5.3 Flash to its Token Pass subscription
Vercel has added GLM 5.3 Flash to Token Pass, bringing Z.ai’s native multimodal coding model to the subscription’s model lineup. The model is available through Vercel’s…
NVIDIA DGX Spark Adds Official Eight-Node Clusters With 1 TB of Memory
NVIDIA has announced official support for eight-node DGX Spark clusters, which raises unified memory to 1 TB and lets developers run frontier-class models such as the…
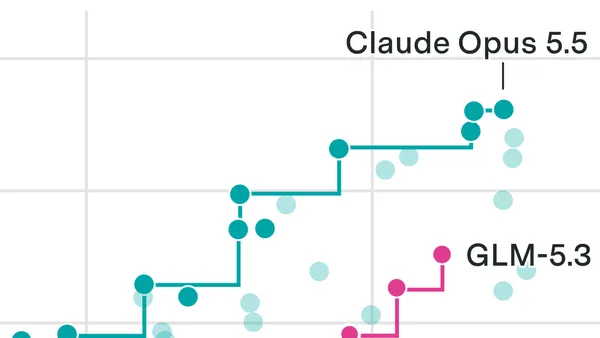
Open-weight AI models trail closed ones by 6-7 months on cyber, Epoch AI finds
Open-weight AI models are roughly 6 to 7 months behind the closed frontier on cybersecurity tasks, according to Epoch AI. Z.ai's GLM-5.3 is the top open-weight model on…
GLM 5.3 from Z.ai arrives on Amazon Bedrock as a managed API
Amazon Web Services has made GLM 5.3, an open-weight model from Z.ai (Zhipu AI), available on Amazon Bedrock through fully managed APIs. According to AWS, access is open…
Baseten Claims Fastest GLM-5 Speeds on Artificial Analysis Benchmark
Baseten says its Model API for GLM-5 reached more than 200 tokens per second in a benchmark by Artificial Analysis, with a time to first token of roughly 200ms.…