Forethought: Automating AI Alignment Work Splits Into Three Distinct Types
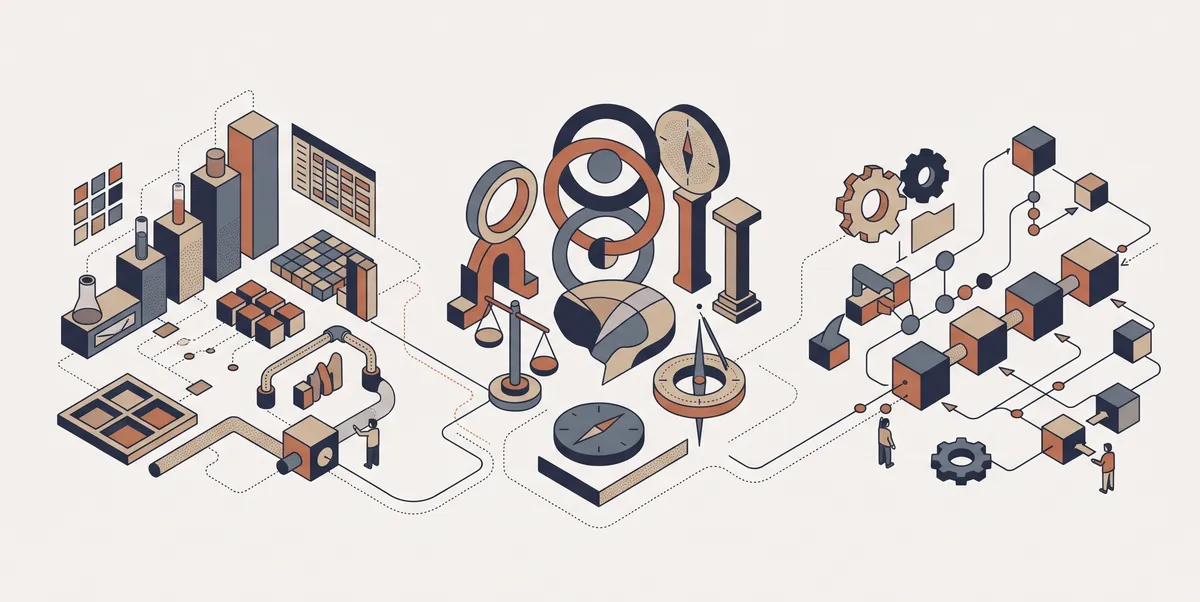
Owen Cotton-Barratt of Forethought argues that efforts to automate AI alignment should be split into three categories: empirical research, conceptual research and direct alignment work. In a post dated 4 November 2026, he says the categories differ in what automation requires, what it achieves and how much damage subtle misalignment could do.
- Owen Cotton-Barratt of Forethought splits automated alignment work into empirical research, conceptual research and direct alignment work.
- He says empirical alignment research fits current AI capabilities best and overlaps heavily with automating capabilities research, so speeding it up is not a priority.
- Conceptual research lacks verifiable signal about progress, but he judges accelerating its automation likely good, if possible.
- Direct alignment work is described as engineering, with examples including RLAIF and monitoring of training.
- The post's goal is to avoid catastrophe long enough to automate conceptual alignment research to a very high quality.
Three buckets with different demands
Cotton-Barratt defines the first category, empirical alignment research, as the design and execution of alignment-relevant experiments for a given notion of what researchers are aiming for. Conceptual alignment research is the theoretical or judgement-driven work that improves understanding of the target and how to achieve it, including how to measure it. Direct alignment work means making particular AI systems more aligned, including through inputs such as training data.
He writes that these buckets are "actually pretty different" in what automation needs, what its impacts are and how much damage subtle misalignment inside the automated systems could cause. For that reason he thinks they should be tracked separately.
Empirical work is the natural fit, conceptual work is harder
According to the post, empirical alignment research is the most obvious match for the AI capabilities arriving now. An AI agent can already design and run an experiment on the relationship between alignment-relevant variables, and agents will probably soon be able to find training methods that raise an alignment benchmark score. The author expects the automated capabilities researchers the field seems on track for to be able to do a lot of this.
He deliberately leaves the design of benchmarks, metrics and evals out of this bucket. In current practice it is tightly intertwined with empirical work, but for automation purposes he sees it clustering with conceptual work. Because the capabilities needed overlap heavily with those for automating AI capabilities research, he does not see accelerating this type of automation as a priority. Instead, it raises the priority of complementary work, especially better specification of the numbers researchers would like to measure or target.
Conceptual research is trickier to automate because there is a lack of verifiable signal about what counts as progress. Cotton-Barratt calls accelerating it "somewhat fraught", partly because it feeds into some dangerous technologies, but concludes it seems likely good to do if possible. Methods he lists include curating training data for finetuning, building scaffolds to elicit more research progress from models, extracting more signal from existing conceptual research data, and building benchmarks for conceptual research capabilities. Even good ideas for benchmarks, without full implementation, would help.
Direct alignment work: engineering rather than science
The author contrasts the two: empirical alignment work is science, while direct alignment work is engineering. Automating it could include careful auditing of particular RL environments or training data, and direct monitoring or supervision of systems during training. He names RLAIF for alignment properties as one form. He also cites Claude 3 Opus's apparent self-alignment as another, though accidental in that case, and suggests it could happen deliberately if the behaviour could be reproduced or generalized.
At the limit, he describes a form of system 2 learning, in which updates are made reflectively by an AI system that is already sufficiently aligned and wishes to become more so, rather than blindly toward a training objective. He acknowledges such a path could be fraught, because it is hard to be confident the starting conditions lie in the right basin of attraction. Its benefit is that it could use the full strength of the AI's cognition, making self-improvement closer to meditation than to self-performed neurosurgery.
Ways to accelerate it include designing setups that deploy AI labour for direct alignment work, designing paradigms that let AI take a more active part in its own alignment, and producing data or scaffolds that improve AI taste at the relevant tasks.
Interactions and priorities
The categories interact. Automated direct alignment techniques can be subjects for empirical experiments, even without good alignment metrics. Automated hill-climbing could yield strong direct approaches, but it depends on adequate metrics. The post warns that if reasoning and implementation outpace measurement, optimising for the best available metrics might produce worse outcomes than following the best-guess direct process.
Cotton-Barratt argues that doing a good job of automating conceptual alignment research should leave one approximately done, since it could prepare the other types and build confidence in their techniques. Strong direct alignment could in principle make systems entirely safe, but he thinks it will be hard to be very confident of that before conceptual automation improves. Each new generation of AI might therefore pose the question of whether alignment techniques transfer or luck runs out.
From an existential risk view, he says the main goal for automating empirical and direct work is to get systems safe enough to robustly avoid catastrophe, "not losing", long enough to automate conceptual alignment research to a very high quality. He names two major uncertainties for priorities. If much loss-of-control risk comes early, more energy should go to "not losing". If the main misalignment risk arrives with systems that perform well even on tasks without verifiable rewards, such as long-term strategy, it makes sense to accelerate the "winning" part and move it earlier in time.
Forethought: Three types of automated alignment work