CodeRabbit Security tops vulnerability benchmark, beating Devin and Codex
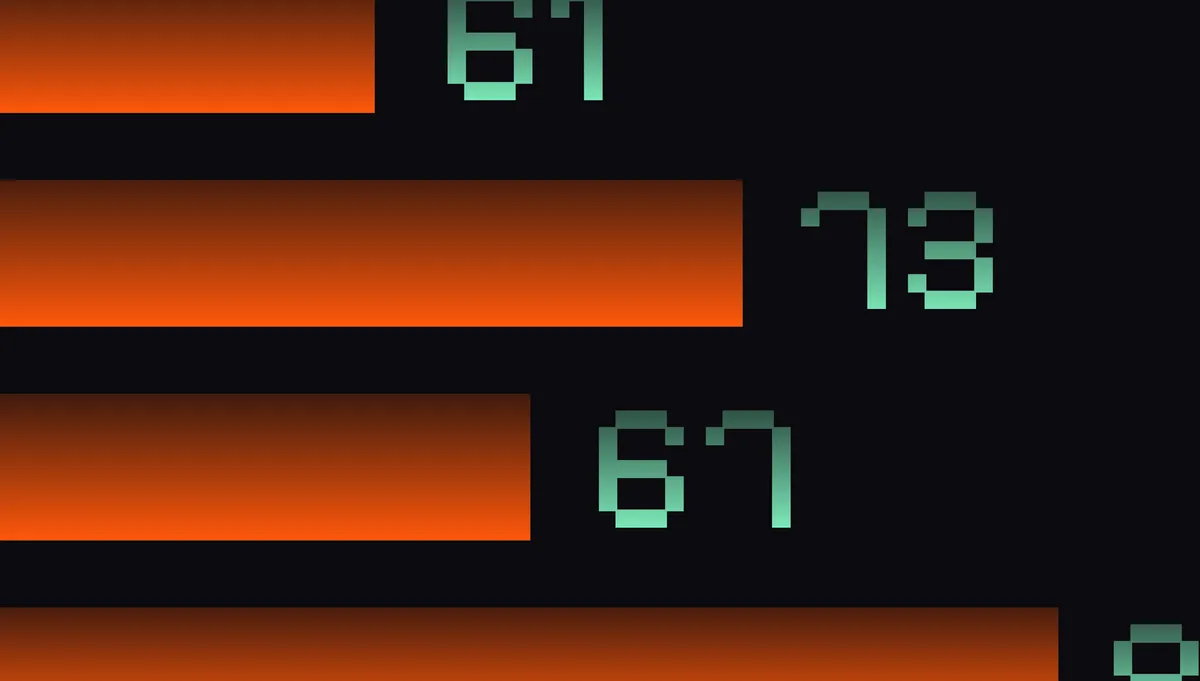
CodeRabbit says its CodeRabbit Security agent detected 86.7% of known vulnerabilities in an internal benchmark of open-source code, ahead of Devin (73.3%), Codex Security Plugin (62.0%) and Claude Security (40.0%). The company published the results itself, describing them as coming from an internal comparative development slice.
- CodeRabbit reports 86.7% vulnerability detection, versus Devin 73.3%, Codex Security Plugin 62.0% and Claude Security 40.0%.
- The test bed has 100 vulnerabilities from 94 repositories, 11 languages and 11 vulnerability families, drawn from GitHub Advisory Database and OSV.
- The results come from an internal comparative development slice and measure detection only, not fix quality.
- CodeRabbit Security works in map, hunt, verify and optional fix stages.
- The company notes prior training exposure to public vulnerabilities remains a limitation.
What the benchmark found
CodeRabbit tested its own product and three other systems on their ability to find known vulnerabilities in open-source repositories. According to the company, the vulnerability detection results were: CodeRabbit 86.7%, Devin 73.3%, Codex Security Plugin 62.0% and Claude Security 40.0%.
CodeRabbit launched CodeRabbit Security a few months ago. The company says it is powered by AI reasoning and can find deep, complex vulnerabilities in code. The benchmark measures only detection. Fix quality is outside the reported score.
CodeRabbit also says the benchmark lets it trace where an analysis fails when a vulnerability is missed. An entry point can go unseen, a useful hypothesis can get lost between stages, or a valid finding can get rejected during verification. Each failure, the company says, points to concrete work its pipeline can iterate on.
How the test was built
The cases come from the GitHub Advisory Database and the OSV database. The test bed covers 100 vulnerabilities across 94 repositories, 11 languages and 11 vulnerability families. By severity, there are 12 critical, 50 high and 38 medium cases. They span authentication, authorization, injection, deserialization, SSRF, XSS, cryptography, data exposure, path handling, protocol integrity and denial of service.
For each case, CodeRabbit identifies the commit that fixed the vulnerability and its direct parent, then checks that the parent contains the vulnerable code. Each system received the vulnerable source code with the advisory and patch withheld. Git history and remotes were removed, and scans ran without network access. The advisory, GHSA or CVE identifier, CWE classification, severity, repository identity, vulnerable file, target lines, fixing commit and patched source were also kept from the benchmark instructions.
CodeRabbit acknowledges a limitation: because the vulnerabilities and repositories are public, prior exposure during model training remains a separate concern. It treats the setup as a controlled test of vulnerability recovery with that in mind.
To earn credit, a finding must match the labeled vulnerability's underlying mechanism at an accepted source location. A different vulnerability in the same file gets no credit, and a matching CWE classification is not enough if the report describes a different attack path. Duplicates count once, and infrastructure failures are tracked separately from model misses.
The four-stage pipeline
CodeRabbit Security works in stages: map, hunt, verify and an optional fix.
- Map: AI agents explore the repository in a secure sandbox and build a system-level map. They identify entry points, trust boundaries, authentication and authorization checks, and a reachability graph linking externally accessible inputs to the code they can affect.
- Hunt: Specialized agents investigate risk areas in parallel, including authorization, injection, business logic, data exposure and AI-specific threats. They trace attacker-controlled input from entry point to sink.
- Verify: An independent verifier reopens the cited paths and checks reachability, safeguards elsewhere in the application, exploitation conditions and whether the evidence supports the claimed impact. Candidates relying on test-only or unreachable code, ignoring existing protections or resting on unsupported assumptions are rejected.
- Fix: For eligible findings, Fix with AI drafts a scoped remediation on a security branch and opens a reviewable pull request or merge request.
CodeRabbit says that when evidence does not support a conclusion either way, it states so rather than treating incomplete analysis as proof of exploitability or of a secure repository.
Mixing models and the role of the harness
CodeRabbit says it compared mixed-model configurations with single-model setups, judging each by the number of known vulnerabilities recovered and how well findings survive investigation, verification and reporting. Using a less expensive model at one stage can lower cost, but it can also reduce the number of correct findings that reach the final report, so changes were evaluated across the whole pipeline.
The company argues that a strong harness lets a good model reach its potential, while a weak model cannot be rescued by even the best harness. It says it invests as heavily in the harness as in model selection, and that it continues to tune model selection and routing as new models become available.
What it means
The figures are vendor-reported and come from an internal development slice, so they are not an independent comparison. CodeRabbit notes that the scoring measures how often a system detects the known target, and that additional findings require separate assessment. For teams evaluating security scanners, the published method shows what the company counts as a valid detection: the right mechanism, an explained exploit path and a supporting source location.