NVIDIA DAQIRI brings real-time GPU processing to scientific instruments
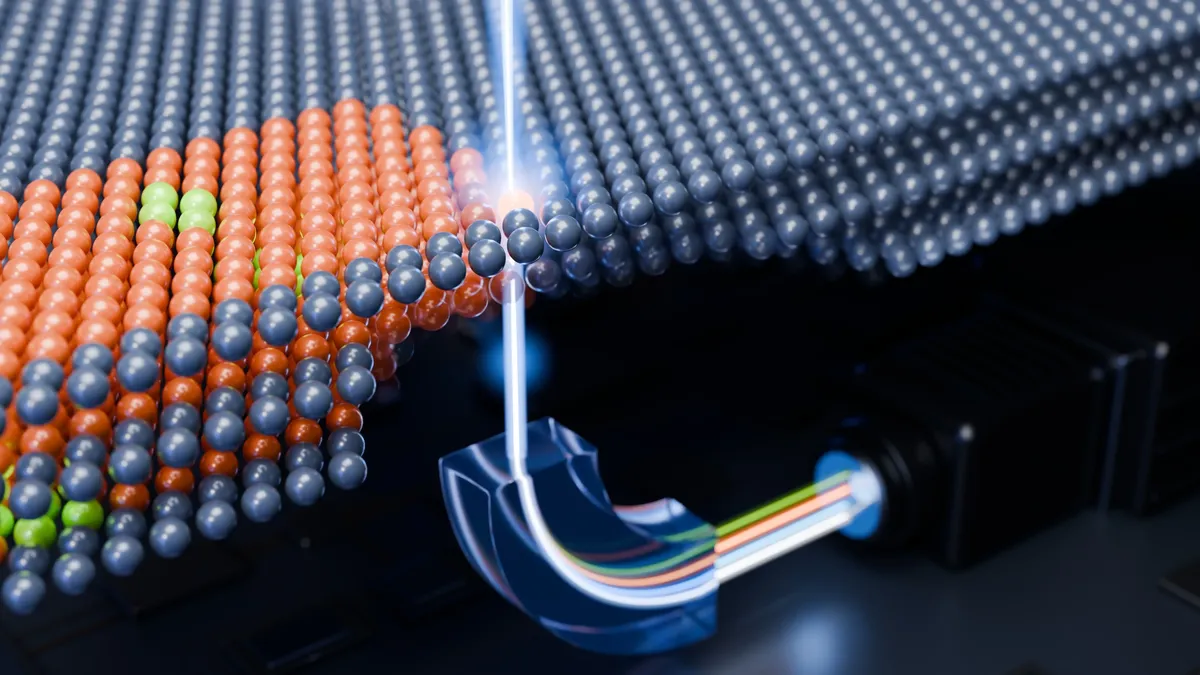
NVIDIA says its DAQIRI software can move high-bandwidth scientific instrument data directly into GPU memory, allowing processing during acquisition. The company highlights a Berkeley Lab electron microscopy workflow that handles more than 500 Gbps while an experiment is running.
- DAQIRI moves instrument data directly into GPU memory for processing during acquisition.
- A Berkeley Lab electron microscopy camera generates more than 500 Gbps.
- The latest release supports hardware packet reordering on ConnectX-7 or newer NICs.
- NVIDIA reports approximately twice the per-core throughput with its ibverbs engine for small packets.
- Direct polling demonstrated 2-4 microseconds of application send-to-receive latency in loopback tests.
A GPU pipeline for data-heavy experiments
DAQIRI is a software-defined data acquisition library for moving instrument and sensor data into GPU-ready workflows. As an NVIDIA Holoscan platform library, it connects measurement-focused sensors with programmable GPU platforms used for scientific analysis, AI inference and feedback applications.
The approach is designed to avoid writing measurements to disk before processing them. For existing Ethernet-capable instruments, NVIDIA says this can create opportunities to add processing and feedback capabilities. For new instruments, it may allow developers to reconsider acquisition constraints from the beginning.
The need is particularly clear in electron energy-loss spectroscopy, or EELS. The technique measures the energy electrons lose when interacting with a sample, helping scientists identify elements and understand how they are bonded. Measurements contain both strong and faint signals, which traditionally requires two separately optimized acquisition processes in rapid succession, followed by alignment and combination of the results.
Berkeley Lab camera processes strong and faint signals together
A high-dynamic-range electron microscopy camera developed at Lawrence Berkeley National Laboratory’s Molecular Foundry captures strong and faint signals together. This simplifies the experimental setup and microscope optics, according to NVIDIA, but produces more than 500 gigabits of data per second.
That stream is more than 500 times faster than conventional EELS data streams. In the Berkeley Lab and NVIDIA workflow, FPGA readout electronics send detector data over Ethernet, while DAQIRI receives packets directly into GPU memory. GPU processing then assembles and corrects detector frames before reducing them to energy-loss spectra.
The processing also improves the spatial information recovered from the detector, enabling submicron spatial resolution from sensor pixels measuring 5 micrometers across. The team can inspect measurements during acquisition and adjust acquisition parameters and regions of interest in real time while processing the incoming data.
Latest DAQIRI release focuses on packet handling and latency
The latest DAQIRI release adds hardware packet reordering for supported NVIDIA ConnectX-7 or newer network interface cards. The NIC can parse sequence fields and place payloads directly into their ordered positions in memory, reducing the need for a separate software reorder copy step and preserving CPU and GPU resources for analysis.
NVIDIA also introduces an ibverbs engine for receiving and transmitting raw Ethernet packets. The company says benchmark tests on NVIDIA DGX Spark, NVIDIA IGX Thor and NVIDIA RTX PRO server platforms showed approximately twice the per-core throughput of the previous default DPDK backend for small packets up to 1024 bytes and data rates greater than 200 Gbps.
A direct polling mode lets an application thread receive and submit packets without handing work to a separate I/O worker. NVIDIA’s summary reports application send-to-receive latency of 2-4 microseconds in cabled loopback benchmark tests. Together, these features target instruments that need ordered data, high throughput and rapid feedback from GPU analysis.
NVIDIA Developer: Enabling Real-Time AI for Scientific Instruments with GPU-Native Data Acquisition